AI Training Dataset for Uzbek Language Released with Nearly 6 Billion Words
The Ministry of Digital Technologies of Uzbekistan has published an open corpus of Uzbek-language texts on Hugging Face, comprising nearly 6 billion words from 5.6 million documents. The dataset is intended for the development of artificial intelligence systems capable of better understanding the Uzbek language and generating content in it.
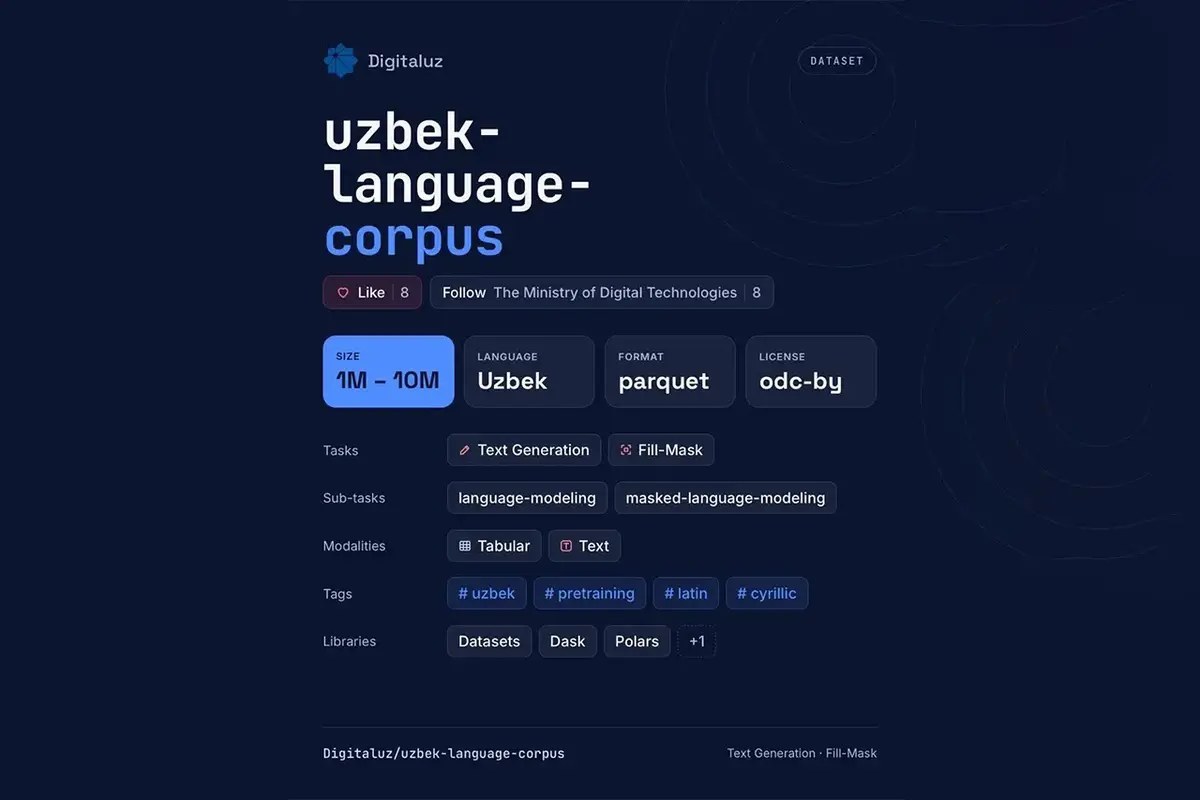
The corpus combines materials in both Latin and Cyrillic scripts. It includes digitized books, newspaper publications, archival texts, legislative documents, Wikipedia articles, web pages, and open publications from Telegram.
Before publication, the texts were processed and selected based on quality, then categorized by industry and thematic areas. According to the ministry, personal data were replaced with special markers, including [PHONE] for phone numbers and [NAME] for names.
The Hugging Face dataset page displays approximately 5.64 million entries. The corpus is presented in Parquet format, with available fields including text, source, thematic area, script used, and word count. Such details allow developers to select materials for specific training tasks. Corpus profile.
Such datasets serve as foundational material for language models: systems learn language patterns, word usage specifics, and conceptual relationships from large text volumes. Support for both scripts is crucial for working with diverse Uzbek-language sources.
The development is part of the implementation of a directive issued by President Shavkat Mirziyoyev on October 21, 2025, during a meeting on the accelerated adoption of AI in public administration, the economy, and the regions. At the time, the head of state emphasized the need for such systems to fully understand the Uzbek language.
The ministry is also working on providing the corpus to developers of leading large language models. The agency reported the start of collaboration with Qwen. Details on the dataset's usage and its integration results into models have not yet been disclosed.
The corpus is available for download on Hugging Face. The profile specifies the Open Data Commons Attribution (ODC-BY) license, which requires attribution when using the database.